Courses
Long-form, sequential courses that build a topic from first principles.
Available now
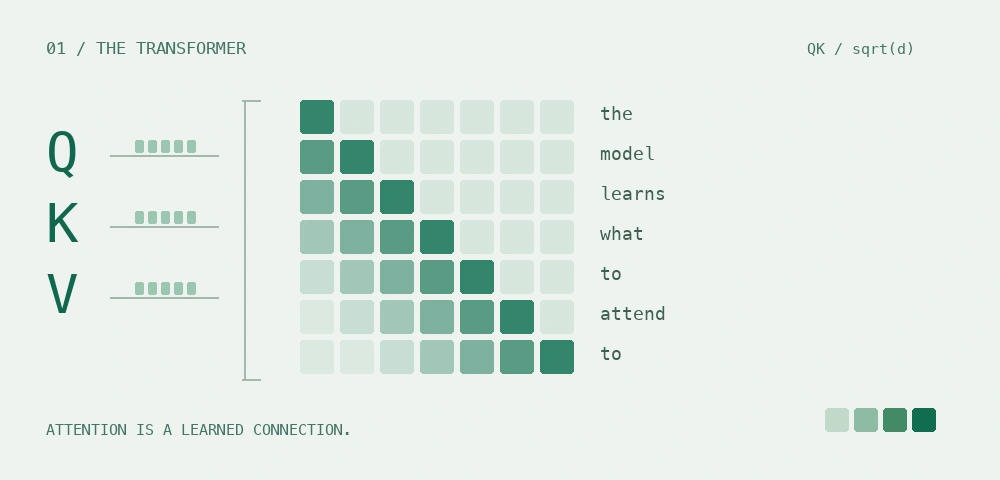
A sequential, build-from-scratch course on the Transformer architecture, from "why did we abandon RNNs?" through to the exact configuration choices in production models shipping in 2026.
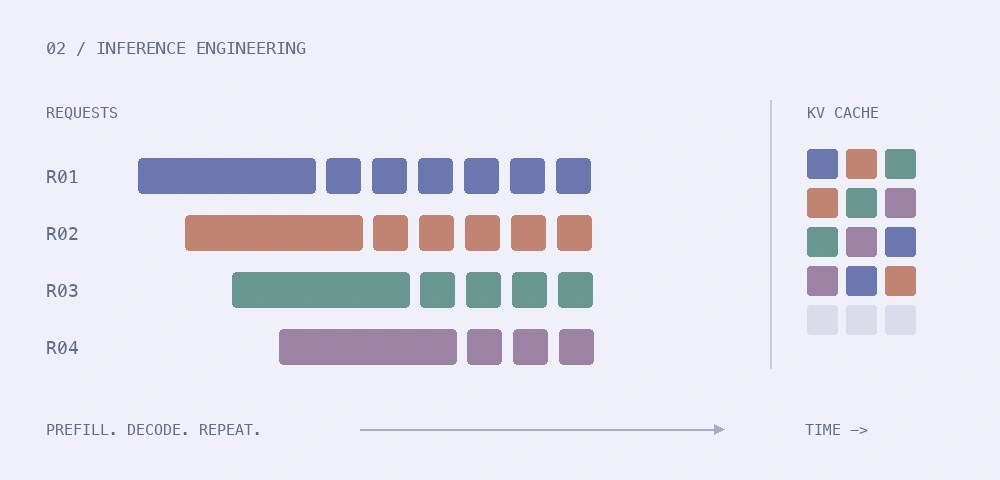
How LLM serving systems actually work, read out of the vLLM and SGLang source. Continuous batching, PagedAttention and RadixAttention, quantization, parallelism, speculative decoding, and how to benchmark any of it honestly.
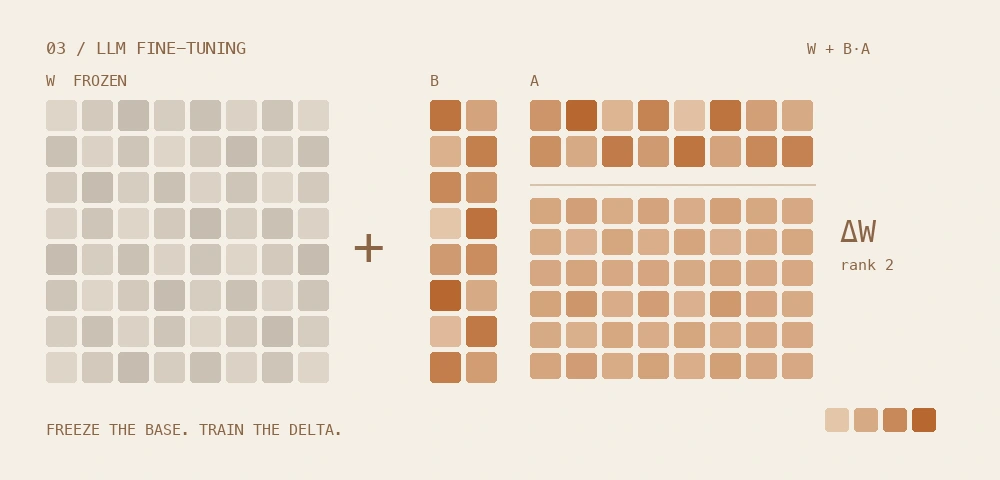
A sequential, derive-it-yourself course on adapting pretrained language models, from "why not just prompt it?" through supervised fine-tuning, LoRA and its relatives, preference optimisation, and RL with verifiable rewards, to the data, evaluation and serving choices behind production 2026 models.
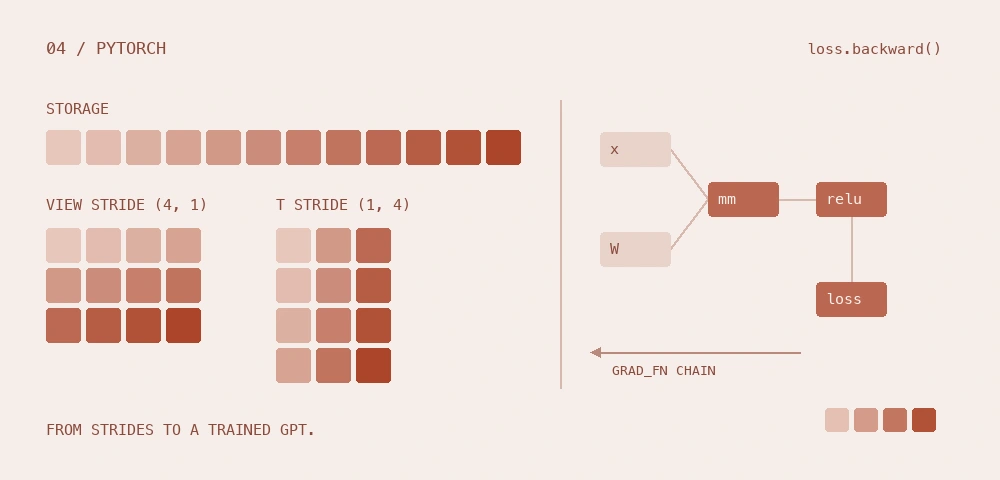
A sequential, test-backed course on PyTorch 2.8, from installing it and reading a tensor's strides through autograd internals, torch.compile, distributed training, custom kernels, export and quantization, ending by building, training, evaluating, fine-tuning and exporting a GPT-style language model from scratch on a CPU.